
STAR: settling the details
On the path to stabilizing STreaming ARchives

hese are the aspects of STAR which I feel haven't been fully settled yet, and a summary of all other feedback to date. Thoughts and pushback welcome! I'll keep an eye out for follow-ups on any of the linked places below, and on responses to this post.
The current draft for the STAR spec in DASL is in PR: https://tangled.org/dasl.ing/dasl.ing/pulls/16/round/2 -- it's a rewrite since the last microcosm STAR version, any inconsistency should defer to the DASL PR.
Main unsettled questions
Q1: Format determinism
- varint: SHOULD vs MUST for readers -- stdlib varint decoders are typically not strict, so it might be nice to make readers checking be a SHOULD.
Update: my position on this is now: we keep the MUST. CAR's DASL spec technically requires it, it's not new strictness. Yeah, lots of implementations will not be compliant if they use stdlib/common varint libraries -- hopefully the interop test vectors nudge them toward being strict.
My compromise position: we do bijou64 instead of varint.
Q2: Metadata $type authority
- authority: should we recommend using domain authority (like NSID)
- with optional
#frag(@bnewbold.net -- can you say more about this? do we have a syntax in atproto for bare nsid with a fragment suffix already?)
- with optional
- my current view is that there is no official authority of STAR
$types. It's useful for content negotiation. producers and consumers usually know who eachother are and why they are talking to eachother, so when i'm processing a$type: atproto-space-repo, it's not an random STAR from the universe. If someone makes an unrelated application profile and uses the same$type, it's only a problem if they start getting collected together. ...- is this naive? we already almost could have been at risk of a collision like that, since I was going to make an independent STAR format for atproto spaces before spaces got on board with adopting STAR. if the adoption had happened later, the "official" application profile might have needed to pick a worse
$typestring to avoid a collision with my independent one, or reuse it "in the same universe" and have more of a risk of actual $type confusion. - i hope that some basic guidance in creating application profiles (prefix it with a name you feel authoritative over, recommend nsid, whatever) can mostly avoid this?
- is this naive? we already almost could have been at risk of a collision like that, since I was going to make an independent STAR format for atproto spaces before spaces got on board with adopting STAR. if the adoption had happened later, the "official" application profile might have needed to pick a worse
Update! require $type to be a utf-8 string, make a SHOULD for constraining it to chars that can be used in a mime type parameter for content negotiation, mention nsid as a possible approach to avoid collisions.
Q3: Data control bytes
Update! There's now a whole post just for Q3:
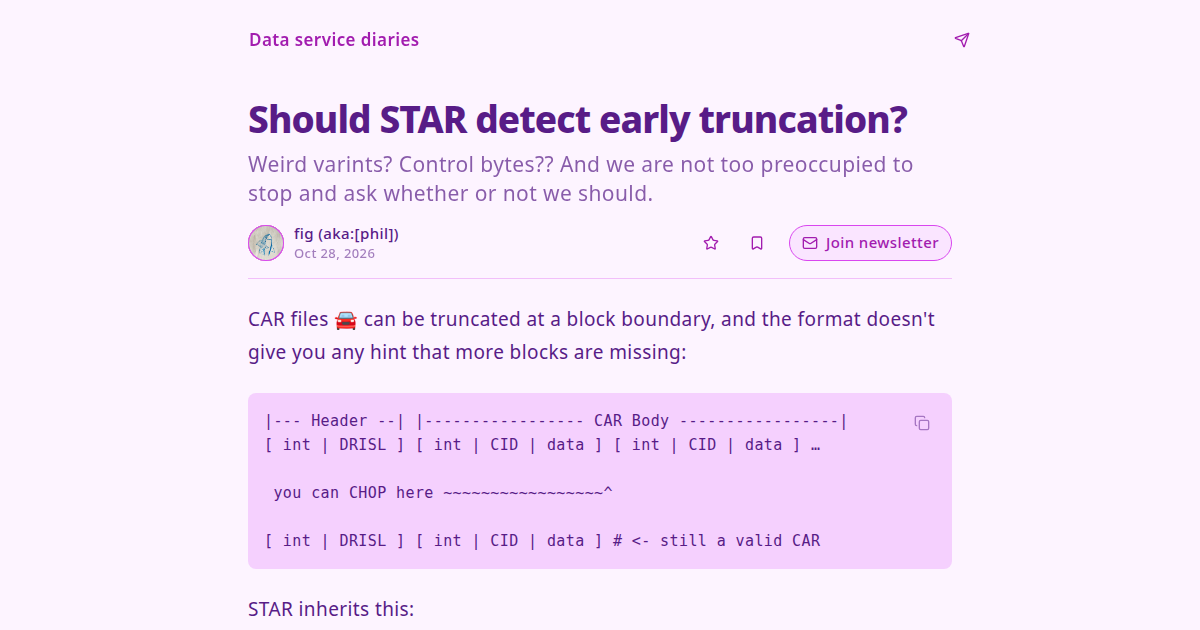
Should STAR detect early truncation? - Data service diaries
Weird varints? Control bytes?? And we are not too preoccupied to stop and ask whether or not we should.
Update update! Probably going with a key prefix shifted up by 1, which looks like this: https://microcosm.tngl.io/star/spec-edits/shifted-key-len.html
No control bytes, but we detect early truncation.
Q4: Format-level maximum sizes
- I dropped them in the DASL draft, since CAR's specs don't list any. The numbers I picked (64MiB meta and keys, 64 GiB values) felt very arbitrary. Application profiles should require smaller limits that suit their needs, and reader implementations should provide interfaces to enforce lower limits before attempting to read any content anyway... so what does a spec-level limit add? I think values should be allowed to be pretty big (readers can even offer chunked value-streaming interfaces), which makes it hard to pick a number that feels like a meaningful backstop for memory exhaustion. But, having no limits specified seems like playing loose with it. Maybe it's fine?
Update: yeah this came to consensus easy enough: no format-level limits, just (strongly) recommend application profiles include limits for meta, key sizes, and value sizes.
Initial dasl.ing issue comments
Link: https://tangled.org/dasl.ing/dasl.ing/issues/21
- Actually there was not really any pushback in this thread, mostly very nice words of support :)))
STAR in atproto spaces PR comments
Link: https://github.com/bluesky-social/proposals/pull/114#pullrequestreview-5536752722
- @ngerakines.me:
$typeshould be be an NSID like all other lexicons so it can be resolved to a lexicon schema to be described, documented, etc. (See Q2)- I like this! Originally I wanted something like domain authority but was worried about name collisions with
$typeNSID, but it makes sense to just consider it like an NSID. I don't think we should pull lexicon in at the format level, but I think applications can choose to handle this like an NSID with resolution etc.
- I like this! Originally I wanted something like domain authority but was worried about name collisions with
- @dholms.at: option example: DASL group maintains a list of STAR profiles (See Q2)
- I don't have a good answer yet for where Application Profiles live. Or what one is, in very specific terms. I need to write that part in the DASL draft. But I don't want to be restrictive in what applications are allowed to require.
- @bnewbold.net: we might recommend folks defining new STAR profiles use NSID in
$type. It might not be ideal to blur or create ambiguity over the namespace of a "protocol-level string" (See Q2) - @matthieu.bsky.team: NSID makes makes publication of a new version of the schema easier (though
com.atprotolexicons are atproto spec). alternatively could use a different string than$typeto avoid confusion. (See Q2)
Review/Feedback (2026-10-16) from @bnewbold.net
Link: https://tangled.org/microcosm.blue/star/issues/2
- Rename this just STAR, from STAR-lite
- Accepted. The v0 'STAR-lite' format for public atproto repos (first shipped with Hubble) will keep the STAR-lite name, and the reference rust implementation might keep using it as a crate name.
- Security section TODOs
- mention allocation size checks
- reference safe CBOR parsing best practices
- can a valid STAR be a valid PNG, PDF, ... etc?
- consumer slow-drip DOS
- STAR and contents are often untrusted inputs
- binary keys, watch for UTF-8 tricks (null bytes, zwj, surrogate chars,)
- format determinism (see Q1)
$typepreference (see Q2)- Termination indicator (see Q3)
- "I don't have a proposal but can brainstorm something simple." please do if you want it @bnewbold.net :)
- Per-block integrity checks, more integrity checks generally
- Provisionally rejected: good integrity checks are high-entropy, increasing post-compression archive sizes if added at a per-block level. (per-record SHA256 on public atproto repositories: 2x compressed size). Many filesystems (btrfs, zfs) and storage engines (rocksdb, fjall) have data integrity checks, and transfer over HTTPS can be early-truncated but otherwise not corrupted in transport, so I'm inclined to allow applications (like Hubble, whose cost is space-efficiency-sensitive) to omit another layer of checks where it's safe to do so. I'm open to lower-overhead options (check over every N blocks? mandatory whole-archive checksum at the end?), but lean toward leaving it as something for the application to solve, given the varying needs.
- Bijou64 discouraged
- Agreed for STAR
- Leaving a TODO unchecked here to pitch DASL on bijou64 more broadly
- Encountering "EOF" (earlier proposal's poor wording choice)
- Dropped that wording in the DASL PR (yeah, was meant as "early input stream end" is an error, not
0x04byte)
- Dropped that wording in the DASL PR (yeah, was meant as "early input stream end" is an error, not
Initial dasl.ing PR comments
Link: https://tangled.org/dasl.ing/dasl.ing/pulls/16/round/2
- @mosh.bsky.social: "parse errors should be considered fatal" -> "must"
- @mosh.bsky.social: dasl spec should have some links out while in HNS status
- @vmx.cx: clarification of canonical varint prefix wording
- @vmx.cx: ordered pairs (sorted vs ordered). suggestion to call it "sequenced" instead of "ordered", other suggestions. Do we need this to be spelled out as a requirement? (or, is it even required?)
- I edited the spec to remove "ordered" in many places, but kept it in the Data pairs description. It's less of a central emphasis now, but still explicitly ordered (it is required imo).
Implementation feedback (2026-10-24) from @bnewbold.net
Link: https://tangled.org/microcosm.blue/star/issues/3
- Note for clarity that the overall meta object can not be empty (
$typerequired) $type: note empty string allowed (or require it be non-empty)- I don't see a reason to require it be non-empty, but am open to hearing one
- must canonical varint be a MUST for readers or can it be SHOULD? stdlib impls tend to accept non-canonical/encodings (see Q1)
- (which stdlibs have varint decoders? golang at least. this is just my own curiosity)
- Semantics of a pair with empty key and empty value are kind of weird, should it be disallowed?
- Provisionally rejecting -- i don't think it's that weird? it would seem like an odd restriction. would be happy for pushback.
Intended changes
TODO: meta strictness
be explicit that readers should reject non-canonical meta, or else note that whether an archive is deterministic depends on that.
TODO: other $type rules
explicitly note that metadata must be present, which is implied since $type is always required. explicitly note that empty-string $type is allowed.
Appendix: earlier Q3 content:
I removed this from the "unsettled questions" section since it's now covered in the new post, but for the record, here's what it originally said:
- Right now there is no explicit end-of-archive signal -- an archive truncated at the boundary of any data pair is a valid archive, at least at the format level. So, unless applications add their own check that covers truncation, they can silently miss data when reading truncated archives. Currently, that will just be an Application Profile guidance: put a "number of records" or "MST root hash" or lthash over the set or checksum of keys or whatever, in the
meta.- I don't think there's a really nice way to do an end-of-archive signal with the current concatenated (len | key | len | val) format. anything in-band would be unfortunate... i suppose we could reserve <empty key | empty val> or something but i don't like it. The only other thing I can see is using an invalid
len... which means a non-canonical len. This seems like a very bad idea, since it ties an internal varint detail to the format, and might lead to unsafe failures with decoders that permit non-minimalvarints on read. I don't like it.
- I don't think there's a really nice way to do an end-of-archive signal with the current concatenated (len | key | len | val) format. anything in-band would be unfortunate... i suppose we could reserve <empty key | empty val> or something but i don't like it. The only other thing I can see is using an invalid
- A control byte between each data pair would provide an opportunity for signalling like end-of-archive. Like,
0xAAmeans "another keypair" (endless scream);0xEEmeans "end of archive" (eeee stop!), etc.- I don't think we'd want any other control bytes, but if we ever did, there'd be a place for that.
- It's not much overhead except in applications with very small keys and values, and/but would be near-free in size when archives are compressed.
- My biggest gripe is aesthetic. It feels like it adds noisiness to the currently-very-simple description. I can get over it if we need it. Do we need it? CAR gets by without, but we're aiming for stricter-than-CAR.
Did you enjoy this article?
Recommend it — Standard Reader surfaces well-loved writing to more readers across the network.